--Comparing Text Strings--
I have two text files to compare: file A and file B file A is nicely formatted with sections, headings etc, for better visibility file B is a linear raw list of strings (really a bunch of machine names) I am trying to compare file A and file B, and locate the strings in each file that don't exist in the other, and vice versa-- in other words, identify unique strings in each file. UNIX utility *diff* works great, so do Windows tools like 'ExamDiff', 'CompareIt!' etc; but they only compare a single occurence of each string pair, and ignore the rests. For instance, I have List A List B ------ ------ abc bcd def def def ijk ghi jkl The result will be: List A List B ------ ------ abc bcd def ijk ghi jkl (Note that the eliminated strings were the ones that followed One-to-One matching) While the expected result is: List A List B ------ ------ abc bcd ghi ijk jkl With both occurences of 'def' being eliminated - with One-to-many comparison. Can anyone suggest a solution? A tool or an script logic? ~@~
Saajha · Aug 14, 2009 2:13 PM · 16,298 views
try http://www.scootersoftware.com... Last edited: 14-Aug-09 04:42 PM
techGuy · Aug 14, 2009 4:37 PM
Just installed and tried it -- still the same issue ..it does the comparison, but only for a single occurrence. I haven't had a chance to look at the options yet though. Thanks! ~@~
Saajha · Aug 14, 2009 4:59 PM
Download the 30 day free trail of arexis merge. This tool works great. http://www.araxis.com/merge/
parajn · Aug 14, 2009 7:07 PM
Have you tried this tool for similar purpose? Will take a look. Thanks! BTW, I was able to get it done on Excel (underrated, but worked great) by playing around with logical comparison formulas. ~@~
Saajha · Aug 18, 2009 12:19 PM
Create two text files. x.txt with abc def def ghi and y.txt with bcd def ijk jkl Issue following commands (at cygwin prompt) //sort and copy unique elements of x to x1 sort -u x.txt > x1.txt //sort and copy unique elements of y to y1 sort -u y.txt > y1.txt //copy lines that appear in the both x1 and y1 to z comm -1 -2 x1.txt y1.txt >z.txt //output lines that appear in x1 only comm -2 -3 x1.txt z.txt //output lines that appear in y1 only comm -2 -3 y1.txt z.txt Works for this limited dataset. Give it a try.
gidilat · Aug 18, 2009 1:34 PM
Thanks @gidilat, for the advice, and welcome to the forum - if you are a new member :-) Just looked through the commands and spotted a minor gotcha.. When you do sort -u and sort the list in order by unique elements, you'd actually get rid of multiple occurrences of each element. Once that's done, it's really a one to one comparison, no? In the above scenario, ALL occurrences of def on list A were eliminated - as they matched def on list B. But if I had, say abc listed twice in list A and did not exist at all in list B, sort -u would remove the second instance of abc in list A, correct? But the goal is to have every single occurrence of abc in list A if it's not present in list B. Thanks again for chiming in. ~@~
Saajha · Aug 18, 2009 4:37 PM
You are changing the goal from "in other words, identify unique strings in each file" to "goal is to have every single occurrence of abc in list A if it's not present in list' A problem needs to defined properly before it can be solved.
gidilat · Aug 18, 2009 7:02 PM
Hmm, so - I said: "...the goal is to have every single occurrence of abc in list A if it's not present in list B" Doesn't that leave each list's strings/elements unique to those of the other list (and hence "...unique strings in each file")? When we compare two files and speak about 'uniqueness', I'd think the reference would be toward uniqueness with respect to each other, and not within oneself. Regardless, I'll buy the fact that 'unique strings in each file with respect to each other' or something similar would've made it little more descriptive. Sorry -- Thanks! So, just for the heck of it - I tried comm without sorting and isolating the unique elements, works just as good as any other alternatives (except Excel) that I tried in the past. It does the comparison, but only gets rid of a single occurrence of the match. ~@~
Saajha · Aug 19, 2009 11:08 AM
This conversation is preserved exactly as it was on the original Sajha.com and can't accept new replies.
Start a New DiscussionYou might be interested in...


-
Room Available for Rent USD 850.00Melrose, MA ·
-
One bed room available for rent USD 1,300.00Germantown, MD ·
-
Malden, MA, United States · Reposted Originally posted
-
Big Room with Parking Next to bus stop USD 1,100.00Everett, MA ·
-
Rooms Available for Rent USD 2,700.00Reston, VA ·
-
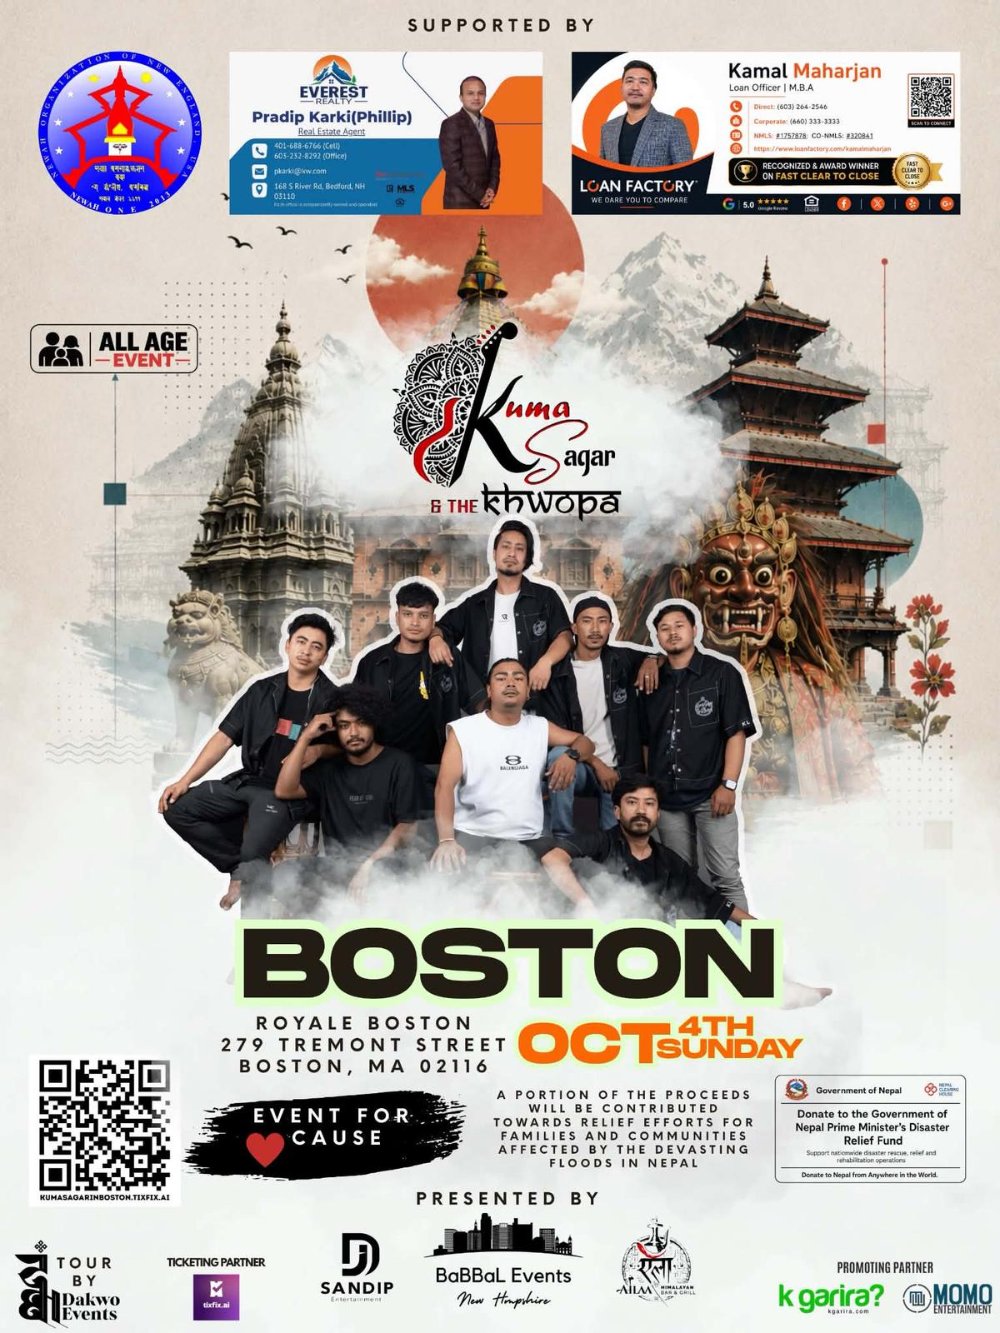 Oct 4, 2026 7:00 PM · Boston / New England · 507 views
-
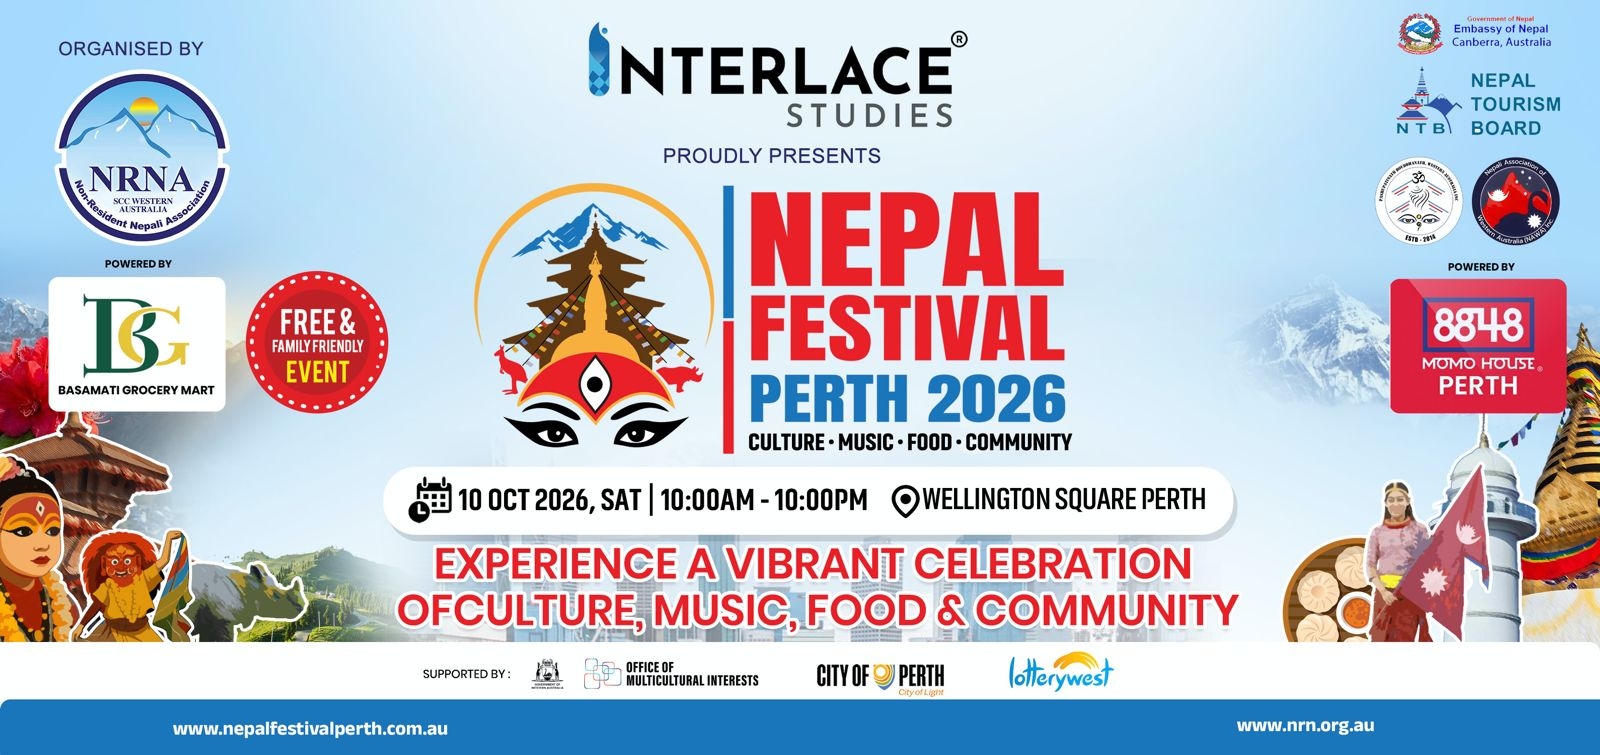 Nepal Festival Perth 2026 FestivalOct 10, 2026 10:00 AM · Perth / Western Australia · 220 views
-
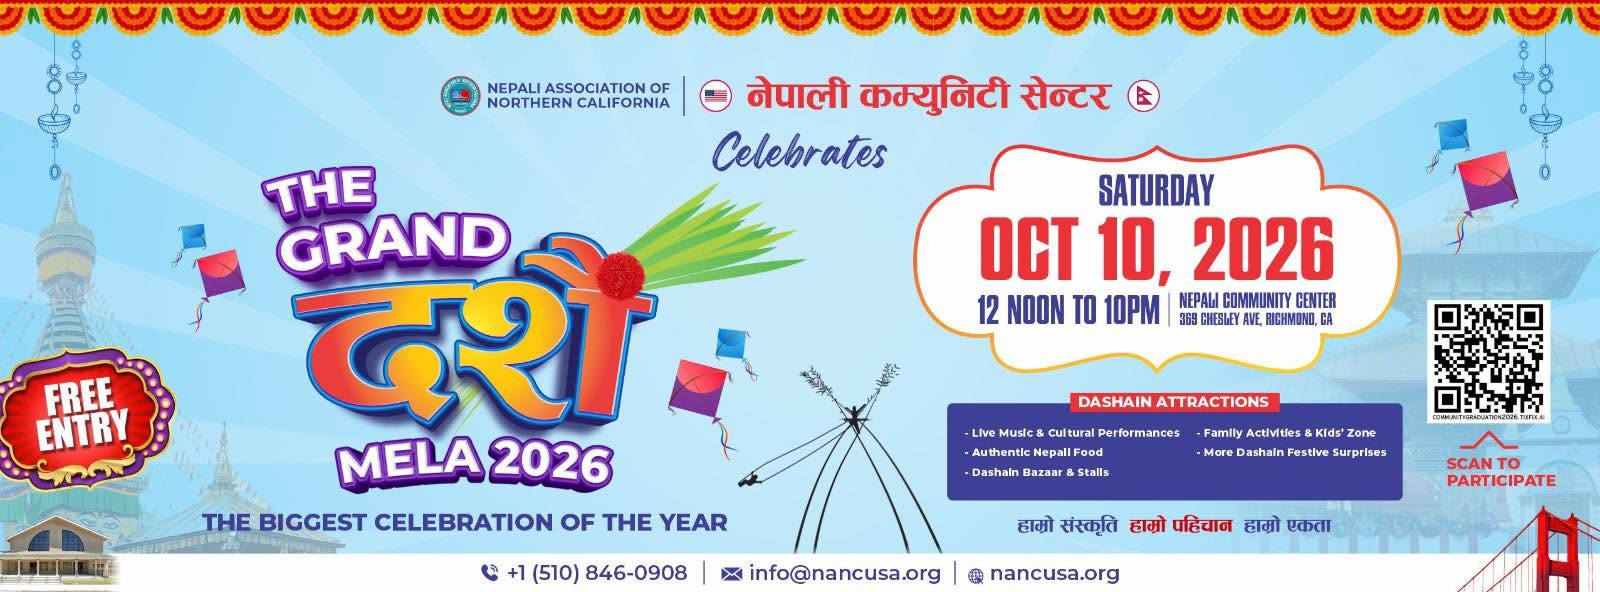 Grand Dashain Mela 2026 FestivalOct 10, 2026 11:00 AM · Bay Area / Northern California · 209 views
-
 Oct 11, 2026 11:00 AM · DMV / Greater Washington · 221 views · Dashain
-
 Dashain Festival Fulpati PartyOct 17, 2026 10:00 PM · Greater London · 183 views · Dashain
-
✓Vianet Communications OtherKathmandu · · 280 views
-
Aama Lama RestaurantMalden, MA · · 238 views
-
Ailaa Himalayan Bar & Grill RestaurantStoneham, MA · · 239 views
-
Ailaa Himalayan Bar & Grill RestaurantBedford, TX · · 214 views
-
Annapurna Curry & Sekuwa House RestaurantManchester, NH · · 218 views